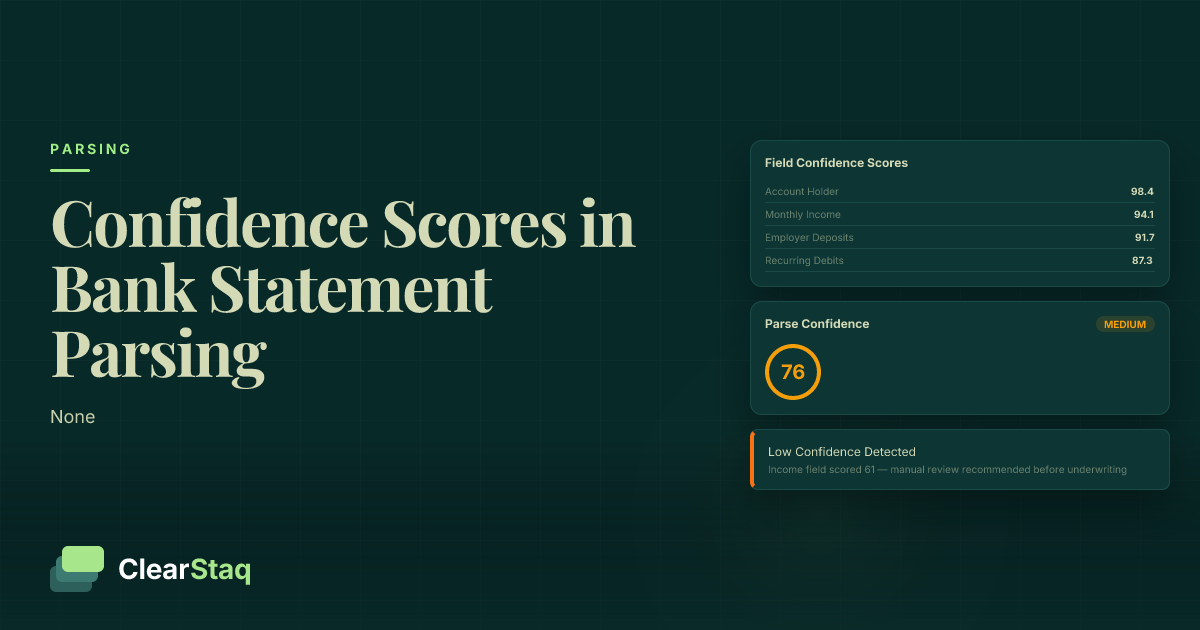
A bank statement parsing confidence score is a numeric value (0 to 1) indicating how certain an AI model is about each extracted data point. Scores above 0.92 support automated acceptance; scores below 0.75 should trigger rejection or re-request. Field-level confidence scoring lets lenders act on specific uncertain values rather than flagging entire statements.
What you'll learn
- A confidence score measures model certainty — not accuracy — and the gap between the two is the calibration problem every lender should understand
- Field-level confidence scores are more actionable than document-level aggregates because they pinpoint exactly which values need human review
- Scores above 0.92 generally support straight-through processing; scores below 0.75 warrant document rejection and resubmission
- Isolated low confidence on a single critical field — while surrounding fields score high — is a potential fraud signal, not just a scan quality issue
- Continuous model fine-tuning on real bank statement data improves calibration over time, reducing unnecessary manual review burden
A bank statement parsing confidence score is a numeric value — typically 0 to 1 — that indicates how certain an AI model is about each piece of extracted data. Scores above 0.92 generally support automated acceptance, while scores below 0.75 should trigger rejection or re-request. Field-level confidence scoring — not just document-level — allows lenders to act on specific uncertain values rather than flagging entire statements.
What Is a Confidence Score in Bank Statement Parsing?
When an AI system extracts data from a bank statement, it doesn't just return values — it returns a measure of how confident it is in each one. That measure is the confidence score: a probability value between 0 and 1 representing the model's certainty about a specific extracted field.
A score of 1.0 means the model is certain. A score of 0.50 means the model is essentially guessing. In practice, most well-calibrated systems produce scores between 0.70 and 0.99 on readable documents, with the gaps below 0.75 flagging fields that need human attention.
Confidence scores exist because automated parsing can't ask for clarification the way a human reviewer can. When an underwriter encounters an ambiguous figure, they pick up the phone or zoom in on the document. A parsing engine needs to communicate its uncertainty numerically — and route the document accordingly.
Scores operate at multiple levels: character, word, field, and document. Understanding which level matters for your workflow determines whether confidence scoring is useful or just decorative.
Confidence Score vs. Accuracy: A Critical Distinction
This is where most articles get it wrong: a 95% confidence score does not guarantee 95% accuracy. The two are related, but they aren't the same thing.
Confidence is what the model believes about its output. Accuracy is whether that output is actually correct. The gap between the two is called the calibration problem, formalized by Guo et al. (2017) in their foundational work on neural network calibration, which demonstrated that modern deep learning models are systematically overconfident.
An overconfident model assigns high scores to extractions that are wrong more often than the score implies. An underconfident model flags correct extractions as uncertain, creating unnecessary manual review burden. Both are costly in lending — but overconfidence is the more dangerous failure mode.
Acting on a high-confidence but incorrect balance figure has real financial consequences. That's why bank statement parsing accuracy headlines like "99.5% accuracy" need to be read alongside calibration data, not in isolation.
Where Confidence Scores Come From
Confidence scores aren't arbitrary — they're computed from several compounding signals:
- Character-level recognition probability: The OCR engine assigns a likelihood to each character it reads based on the pixel pattern it sees. Ambiguous characters like "0" vs. "O" or "1" vs. "l" drive these probabilities down.
- Language model post-processing: A secondary model adjusts raw character scores based on expected patterns. A field expected to contain a date gets penalized if it doesn't match a known date format. A dollar amount gets flagged if it contains letters.
- Image quality factors: Resolution, scan angle, contrast, and shadow all degrade the input signal. An image below 300 DPI produces noisier character-level estimates.
- Format-specific calibration: A tool trained extensively on Chase statements will score Chase-format fields more reliably than an unfamiliar regional bank template. Generic OCR tools lack this calibration.
Document-Level vs. Field-Level Confidence: Why the Distinction Matters
Most generic OCR tools return a single confidence score for the entire document. That number is useful as a triage signal — but it's far too blunt for underwriting decisions.
Consider this scenario: a bank statement scores 0.97 at the document level. That sounds reliable. But the running balance column on page 3 scores 0.61, while every surrounding field scores above 0.94. The document-level aggregate completely masks a critical problem.
Field-level confidence solves this. Instead of one score per document, the system returns a score for every extracted value: account number, transaction date, transaction amount, running balance, memo line, opening balance, closing balance. This enables surgical review — underwriters inspect only the specific fields in doubt, not the entire statement.
The regulatory implication is real. CFPB data accuracy standards require lenders to act on uncertain data with specificity. Flagging an entire document because one field is uncertain wastes time and creates friction for borrowers. Flagging only the uncertain field is both more efficient and more defensible.
How Field Scores Are Aggregated Into a Document Score
Two approaches dominate: weighted average and minimum-field.
A weighted average sums all field scores and divides by field count (sometimes weighting critical fields more heavily). It produces a smooth aggregate that's easy to display — but it can hide a critically low-confidence field behind a sea of high-confidence ones.
A minimum-field approach sets the document score equal to the lowest-scoring field, or at least flags when any field falls below a defined floor. This is safer for high-stakes lending decisions because one unreliable critical field is enough to invalidate a decision.
Multi-page statements add complexity. If months 1 through 5 scan cleanly and month 3 is a low-quality photocopy, the per-page confidence variance must be preserved in the output — not averaged away.
Which Fields Carry the Most Weight for Underwriting Decisions
Not all fields are equal. Lenders should weight their review queues by field importance, not just by confidence score alone.
| Field | Underwriting Importance | Recommended Auto-Accept Threshold |
|---|---|---|
| Ending balance | Critical | ≥ 0.95 |
| Average daily balance | Critical | ≥ 0.95 |
| Total deposits | Critical | ≥ 0.95 |
| NSF count | High | ≥ 0.92 |
| Transaction dates | Medium | ≥ 0.90 |
| Transaction amounts | Medium | ≥ 0.90 |
| Payee names | Lower | ≥ 0.80 |
| Memo lines | Lower | ≥ 0.75 |
Which Bank Statement Fields Have the Lowest Confidence Scores (and Why)
Generic OCR literature talks about confidence scores in the abstract. What it rarely addresses is which specific fields in a bank statement consistently produce low scores — and why. This is the knowledge that actually matters for underwriting teams.
The most problematic fields include:
- Handwritten memo lines: Freeform text with no structural pattern for the model to anchor on. Even partial handwriting on an otherwise digital document sends confidence scores down sharply.
- Running balance columns: Right-aligned numeric columns frequently misalign in scanned documents or multi-column layouts, causing the parser to associate values with the wrong rows.
- Non-standard date formats: Regional banks using DD/MM/YYYY where the parser expects MM/DD/YYYY — and international statements with written month names in non-English languages — generate systematic uncertainty.
- Multi-currency statements: Currency symbol ambiguity ($ vs. CAD$ vs. AU$) and decimal separator differences (1,234.56 vs. 1.234,56) cause both OCR and post-processing models to flag values.
- Micro-print transaction references: Reference numbers in 6pt font, common in older bank PDF templates, push character-level recognition probabilities below reliable thresholds even on clean digital documents.
Understanding these patterns helps underwriting teams prioritize their review queues correctly. To learn more about preventing these errors from propagating downstream, see our guide on how to reduce manual OCR errors in loan document processing.
How Document Format Affects Field Confidence
The format of the document itself is often the dominant factor in confidence scores — more than the bank, the content, or the field type.
- Digital-native PDFs (generated directly from bank software): highest confidence, cleanest text layer. The parser reads the embedded text rather than interpreting pixels.
- Scanned PDFs: Image quality degrades character recognition. Resolution below 300 DPI significantly lowers scores across all fields.
- Photographed statements (mobile captures): lighting variation, perspective distortion, and shadow introduce noise that OCR engines struggle with. Even a well-photographed statement rarely matches scanned quality.
- Password-protected PDFs: Decryption artifacts can corrupt the text layer, causing the parser to fall back to image-based extraction with correspondingly lower confidence.
How Bank Format Variation Impacts Confidence Across Institutions
Format consistency is as important as document quality. Understanding the format differences between major bank statements illustrates why calibration matters so much.
- Major national banks (Chase, Bank of America, Wells Fargo): highly consistent templates, well-represented in training data, high confidence scores across all field types.
- Regional credit unions: Non-standard layouts, sometimes plain-text exports with inconsistent column alignment, variable confidence scores even on digital-native PDFs.
- International banks: Character encoding differences, right-to-left scripts, non-Latin numerals, and non-standard date conventions compound to produce lower scores across almost every field.
This is why a parsing engine needs format-specific calibration — not generic OCR — to score reliably at scale. A tool trained on 900+ bank formats produces fundamentally different results than one built on generic document data.
The Three-Tier Threshold Model: Auto-Accept, Review, Reject
Most articles describe confidence tiers in vague terms. Here are the concrete thresholds that work in practice — with the reasoning behind each.
Tier 1 — Auto-Accept (≥ 0.92): Data processes straight through with no human review. The system trusts the extraction and writes it to the database. Appropriate for high-volume digital-native statements from well-represented bank formats. For critical numeric fields like ending balance, consider raising this threshold to 0.95.
Tier 2 — Human Review (0.75 to 0.91): The document is flagged, but only the specific low-confidence fields are highlighted for the underwriter. The reviewer inspects those fields — not the entire statement. This keeps review time per document low while ensuring uncertain values aren't acted on blindly.
Tier 3 — Reject / Re-request (< 0.75): Document quality is too poor for reliable extraction. The system automatically requests a resubmission — ideally a digital-native PDF from the bank's portal rather than a photograph or a third-generation photocopy.
These thresholds should be calibrated to the specific use case. A mortgage lender with a long underwriting cycle may set the auto-accept threshold at 0.95. An MCA lender reviewing income trends at high volume may accept 0.90 for descriptive fields. The key is to document threshold decisions and maintain an audit trail for compliance purposes — CFPB guidance on automated underwriting requires exactly this.
Setting Thresholds by Field Type, Not Just Document Type
A single threshold applied to every field is too crude. Apply stricter thresholds to critical numeric fields than to descriptive ones:
- Auto-accept ending balance only at ≥ 0.95
- Auto-accept total deposits only at ≥ 0.95
- Auto-accept transaction amounts at ≥ 0.90
- Auto-accept payee names at ≥ 0.80
- Auto-accept memo lines at ≥ 0.75
Building a field-weighted threshold matrix sounds complex, but in practice it's a simple configuration table. The payoff is a review queue that correctly prioritizes uncertain critical fields over uncertain descriptive fields.
What Happens to a Loan Application When Confidence Is Too Low
The workflow downstream of a low-confidence flag matters as much as the flag itself.
For Tier 2 (review queue): the underwriter receives a highlighted view of the parsed output showing exactly which fields are uncertain and by how much. They verify those specific fields against the source document and either confirm or correct the extraction. The corrected value feeds back into the system.
For Tier 3 (rejection): the system auto-generates a plain-language resubmission request. If the borrower genuinely can't provide a digital-native PDF — because they only have physical statements — the application routes to an alternative verification path, such as bank login verification or manual review by a senior underwriter.
See Field-Level Confidence Scores Routing Documents in Real Time
Want to see how confidence score thresholds move your documents through auto-accept, review, and rejection — live? Book a demo and upload a sample statement to watch ClearStaq's threshold model in action.
High Confidence Doesn't Always Mean Correct: Understanding Calibration
Calibration is the property that makes confidence scores meaningful rather than decorative. A well-calibrated model produces scores where a 0.85 confidence prediction is correct approximately 85% of the time on held-out data. A poorly calibrated model produces 0.95 scores that are correct only 80% of the time — overconfidence that misleads lenders into skipping review on unreliable extractions.
Expected Calibration Error (ECE) is the standard measure: the average difference between predicted confidence and empirical accuracy across a test set. Lower ECE means the scores are more trustworthy as probability estimates.
How can lenders spot a miscalibrated parser? Compare a sample of parsed outputs against manually verified ground-truth statements. If fields scoring 0.90 to 0.95 have an error rate well above 5-10%, the model is overconfident in that range. If fields scoring 0.75 to 0.85 are almost always correct, the model is underconfident and creating unnecessary review burden.
A confidence score is only useful if it's predictive. A score of 0.90 that's right 70% of the time gives lenders false assurance and leads to systematic underwriting errors. Ask your parsing provider for calibration data — not just headline accuracy numbers.
How Continuous Fine-Tuning Improves Calibration Over Time
Calibration isn't fixed at training time. Models trained on a larger, more diverse corpus of real bank statements produce better-calibrated scores because they've encountered more edge cases — unusual fonts, rare regional bank formats, degraded scans.
Active learning accelerates this improvement. When a human reviewer corrects a low-confidence extraction, that correction becomes a labeled training example. The model learns which patterns produced the wrong high-confidence output and adjusts its internal probability estimates accordingly.
Format-specific fine-tuning matters here too. A model calibrated on 900+ bank formats produces more reliable scores for a regional credit union than a generic OCR model — because it has seen that credit union's specific layout before, or at minimum a layout similar enough to make confident predictions.
How Confidence Scores Connect to Fraud Detection
This connection is the most underappreciated aspect of confidence scoring in lending — and no competitor makes it explicit.
A low confidence score on a field isn't always a document quality problem. It can be a fraud signal.
Here's the key insight: a legitimately scanned bank statement will produce consistently low confidence across all fields on a poorly scanned page. The noise is uniform — poor lighting, low resolution, misaligned scan angle. What's abnormal is selectively low confidence on specific fields while surrounding text scores high.
Consider this example: every field on a statement scores above 0.94 — except the ending balance, which scores 0.61. That pattern is inconsistent with poor scan quality. It's consistent with targeted content manipulation, where the original ending balance was replaced with a different value, disrupting the text layer in that specific region only.
This connects directly to PDF metadata analysis: a document with high overall field confidence but metadata indicating it was last modified in a consumer image editor is a compound risk indicator. Neither signal alone is conclusive. Together, they represent an elevated fraud probability that warrants escalation, not just data quality review.
Isolated Low-Confidence Fields vs. Uniform Low Confidence
Training underwriters to read patterns of confidence scores — not just individual scores — is one of the highest-leverage process improvements a lending team can make.
- Uniform low confidence across the document: Consistent with poor scan quality. Likely legitimate but unreadable — request resubmission.
- Isolated low confidence on balance or deposit fields while surrounding fields are high: Possible targeted alteration. Escalate to fraud review, don't just request resubmission.
- Gradually decreasing confidence across pages: Consistent with a multi-page document where later pages were photographed in worse lighting. Quality issue, not fraud signal.
Cross-Referencing Confidence Signals with Fraud Indicators
Confidence score anomalies are most powerful when they cross-reference against other fraud signals. ClearStaq's 27 fraud signals analyzed during parsing can validate or elevate a low-confidence field finding:
- A low-confidence running balance that also fails the mathematical balance check (opening balance + deposits − withdrawals ≠ ending balance) is a high-priority escalation, not a data quality flag.
- PDF metadata showing the document was last opened or modified in Adobe Illustrator or GIMP raises the stakes on any low-confidence numeric field in the same document.
- Round-number deposit patterns combined with an isolated low-confidence balance field constitute a compound risk signal that no single check would catch alone.
Building a Review Workflow Around Confidence Score Outputs
Confidence scores are only valuable if your operational workflow is designed to act on them correctly. Here's how to operationalize them.
Straight-through processing (STP) should be defined by document type and field combination, not just overall score. Digital-native PDFs from national banks with all critical fields above 0.95 qualify for no-touch processing. Scanned documents, even if aggregate confidence is high, may warrant a lighter-touch spot-check.
Exception queue design matters. Not every flagged document belongs in the same queue. Route documents with fraud signal cross-references to a senior underwriter or fraud analyst. Route documents flagged only for data quality to a data entry reviewer who can request resubmission. Keep these queues separate.
Audit trail requirements: Log every confidence score, threshold decision, and human override. When a reviewer accepts a field that the system flagged as uncertain, that override should be recorded with a timestamp and reviewer ID. This documentation is essential for regulatory examination and for identifying systematic override patterns that may indicate process problems.
A well-tuned threshold model should auto-accept 70 to 80% of clean digital-native statements and flag only the genuinely uncertain cases. If your review queue is larger than 20-30% of volume, your thresholds are likely too conservative — or your document intake quality needs attention.
Multi-Statement Packages: Aggregating Confidence Across 3 or 6 Months
Most lenders request 3 to 6 months of bank statements. Confidence scoring across a package requires a different logic than scoring a single document.
The safest approach is a minimum-month rule: if any statement in the package scores below the Tier 3 threshold (0.75) on a critical field, the entire package is flagged — do not average away a bad month. A borrower's March statement that scores 0.61 on ending balance doesn't become acceptable because January and February scored 0.96.
More subtly: inconsistent confidence across a 6-month package can itself be a fraud signal. If months 1 through 5 score consistently above 0.94 and month 6 scores 0.61, the variance pattern is suspicious. Legitimate document quality variation doesn't typically jump from excellent to poor for a single month without explanation.
Confidence Scores in Non-Technical Underwriting Dashboards
Raw API confidence values like 0.847362 are not useful for underwriters who aren't data scientists. The interface between the parsing engine and the review workflow needs translation.
Best practices include:
- Translate numeric scores to green / amber / red field highlights in the document viewer
- Highlight specific uncertain fields in the parsed output rather than displaying a single score
- Provide plain-language context: "Running balance on page 3 could not be read with high certainty — please verify manually"
- Show the confidence tier (Auto-Accepted / Under Review / Rejected) prominently, with the specific fields that triggered the tier visible on click
How ClearStaq Reports Confidence Scores in the API Response
ClearStaq returns field-level confidence scores in every API response — not just a document-level aggregate. Every extracted field object contains a value key and a confidence key, a float between 0 and 1.
Developers can filter or sort fields by confidence to build conditional logic — for example, only write a field to the database if its confidence is ≥ 0.92, and trigger a review webhook for anything below that threshold. ClearStaq also includes a document_type field in the response — distinguishing digital-native, scanned, and photographed documents — so developers can apply different threshold logic by document type without building their own classification layer.
For non-technical reviewers, the ClearStaq dashboard renders the same data as color-coded field highlights in the document view. The same confidence data powers both the API and the UI. Learn more about integrating these outputs in the ClearStaq API documentation.
The 900+ format-specific calibration embedded in ClearStaq's bank statement parsing platform means the confidence score for a Chase statement is benchmarked against Chase-specific extraction patterns — not a generic OCR baseline. This produces materially more reliable scores for both national banks and regional credit unions.
Sample API Response: Confidence Scores in Practice
A simplified ClearStaq API response for a parsed statement looks like this:
{
  "document_type": "digital_native",
  "statement_period": {
    "start": "2024-03-01",
    "end": "2024-03-31",
    "confidence": 0.98
  },
  "ending_balance": {
    "value": 14823.47,
    "confidence": 0.97
  },
  "total_deposits": {
    "value": 8200.00,
    "confidence": 0.96
  },
  "average_daily_balance": {
    "value": 12104.83,
    "confidence": 0.94
  },
  "running_balance_page_3": {
    "value": 9441.22,
    "confidence": 0.61,
    "flag": "low_confidence"
  }
}
In this response, a developer would write conditional logic: if running_balance_page_3.confidence < 0.75, trigger the review webhook with the field name and value. The underwriter receives a targeted alert, not a generic "document flagged" notification. Confidence scores are available on every parsed field — not just a predefined subset.
{
  "status": "success",
  "fraud_score": 57,
  "transactions": 47,
  "bank": "Chase",
  "processing_time_ms": 238
}How Confidence Scores Improve as ClearStaq's Model Is Fine-Tuned
Each corrected extraction from the human review queue feeds back into model retraining. A reviewer who corrects a misread running balance adds a labeled example to the training set, helping the model recognize that specific pattern more reliably in future documents.
Format-specific improvements compound across the user base. Adding calibration data for a new regional bank format improves confidence scores for that format for every lender using ClearStaq — not just the one who submitted the correction. ClearStaq publishes calibration metrics so lenders can verify that confidence scores are predictive rather than arbitrary, and can monitor score reliability over time as the model improves.
Frequently Asked Questions
What is a confidence score in bank statement parsing?
A confidence score in bank statement parsing is a numeric value between 0 and 1 that indicates how certain the AI model is about each extracted data point. A score of 0.95 means the model is highly confident in the extracted value, while a score of 0.60 signals significant uncertainty. Field-level confidence scores are more useful than document-level scores because they identify exactly which values require human verification.
What is an acceptable confidence threshold for automated data extraction?
For automated acceptance without human review, a confidence threshold of 0.92 or higher is generally appropriate for critical financial fields like ending balance and total deposits. Scores between 0.75 and 0.91 should route to a human review queue, and scores below 0.75 typically warrant rejecting the document and requesting a higher-quality submission. Thresholds should be calibrated based on the stakes of the decision and the specific fields being extracted.
Can AI parsing make errors on bank statements even with a high confidence score?
Yes. A high confidence score reflects the model's certainty, not guaranteed accuracy — this is the calibration problem. An overconfident model may assign a 0.95 score to an extraction that is factually wrong. Lenders should verify that their parsing provider publishes calibration data showing that confidence scores predict actual accuracy, and should validate parsed outputs against known ground-truth statements periodically.
What does a low confidence score mean in document extraction?
A low confidence score means the AI model could not reliably read or interpret a specific field — typically due to poor image quality, an unfamiliar document format, or ambiguous text. However, when a low-confidence score appears on a single critical field while surrounding fields are high-confidence, it can indicate deliberate document alteration rather than a simple quality issue, making it a potential fraud signal worth escalating.
How do lenders handle low-confidence parsed data?
Lenders typically route low-confidence extractions to a human review queue where underwriters inspect the specific flagged fields rather than the entire document. For very low scores, the system automatically requests a resubmission in a higher-quality format such as a digital-native PDF directly from the bank's portal. Audit trails of all confidence scores and threshold decisions are maintained for regulatory compliance.
Know Exactly Which Values to Trust — Before They Reach a Credit Decision
Stop treating every flagged document the same way. ClearStaq's field-level confidence scores tell you exactly which values to trust, which to review, and which to reject — before a bad extraction reaches a credit decision. Book a demo to see it in action.
Frequently Asked Questions
What is a confidence score in bank statement parsing?
A confidence score in bank statement parsing is a numeric value between 0 and 1 that indicates how certain the AI model is about each extracted data point. A score of 0.95 means the model is highly confident in the extracted value, while a score of 0.60 signals significant uncertainty. Field-level confidence scores are more useful than document-level scores because they identify exactly which values require human verification.
What is an acceptable confidence threshold for automated data extraction?
For automated acceptance without human review, a confidence threshold of 0.92 or higher is generally appropriate for critical financial fields like ending balance and total deposits. Scores between 0.75 and 0.91 should route to a human review queue, and scores below 0.75 typically warrant rejecting the document and requesting a higher-quality submission. Thresholds should be calibrated based on the stakes of the decision and the specific fields being extracted.
Can AI parsing make errors on bank statements even with a high confidence score?
Yes. A high confidence score reflects the model's certainty, not guaranteed accuracy — this is the calibration problem. An overconfident model may assign a 0.95 score to an extraction that is factually wrong. Lenders should verify that their parsing provider publishes calibration data showing that confidence scores predict actual accuracy, and should validate parsed outputs against known ground-truth statements periodically.
What does a low confidence score mean in document extraction?
A low confidence score means the AI model could not reliably read or interpret a specific field — typically due to poor image quality, an unfamiliar document format, or ambiguous text. However, when a low-confidence score appears on a single critical field while surrounding fields are high-confidence, it can indicate deliberate document alteration rather than a simple quality issue, making it a potential fraud signal worth escalating.
How do lenders handle low-confidence parsed data?
Lenders typically route low-confidence extractions to a human review queue where underwriters inspect the specific flagged fields rather than the entire document. For very low scores, the system automatically requests a resubmission in a higher-quality format such as a digital-native PDF directly from the bank's portal. Audit trails of all confidence scores and threshold decisions are maintained for regulatory compliance.
ClearStaq Team
Product Team
The ClearStaq team builds AI-powered tools for bank statement parsing, fraud detection, and income verification.